



Hello
Recently I figured out that one node is slower then the others due to different raid configuration on different nodes. So I decided to rebuild raid on that slow node to meet configuration of other nodes. I turned node down, rebuild raid, copied all data back, started node and it hunged for hours in recovery. Turned out there were delete on one table during node shutdown. And It went replaying delete vectors. And then I found this article https://my.vertica.com/hpe-vertica-troubleshooting-checklists/node-recovery-checklist/
I misunderstood that Data size ment the hole database data size and not the rocovering table data size. So there I made a huge mistake and stoped the node, moved ahm and started the node. So now I see my node fully recreating all projections from buddy nodes.
Can anybody point me if there is any option to advance that single node ahm or to advance checkpoint epoch of the projections living on that node so I can stop this disaster. They all are in a valid state except for one single table as they all already passed incremental recovery before I advanced ahm on other nodes?
please any help)


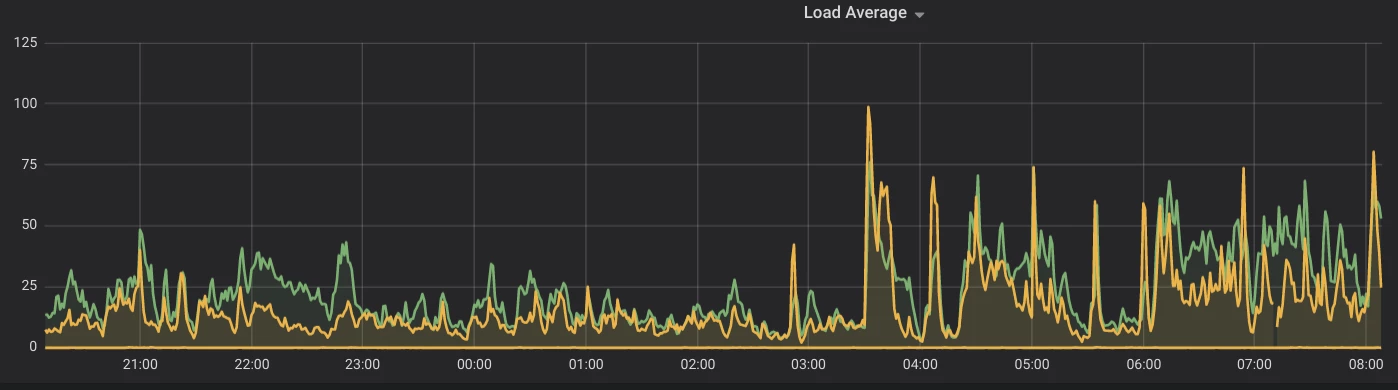 yellow one is an outlier, green one is a one of the other nodes.



