



I would usually expect and observe approximate_count_distinct() to be much more performant than count(distinct). But here's one case where it is actually significantly slower. I am looking for an explanation why that is the case and also some kind of a general applicability scope for approximate_count_distinct(), since it looks like its benefits do not always work
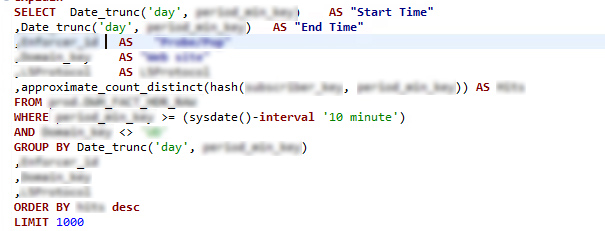
it feels like when combined with a GROUP BY each group adds a little bit of an overhead for approximate_count_distinct, eventually reaching the point of diminishing returns. Just a guess.




