We observe high cpu usage on all nodes of cluster. It occurs second day in row and lasts for several hours in each day (3 hours in a first day and 4 hours in a second).
We had to turn off out ETL while CPU usage growth.
It looks like: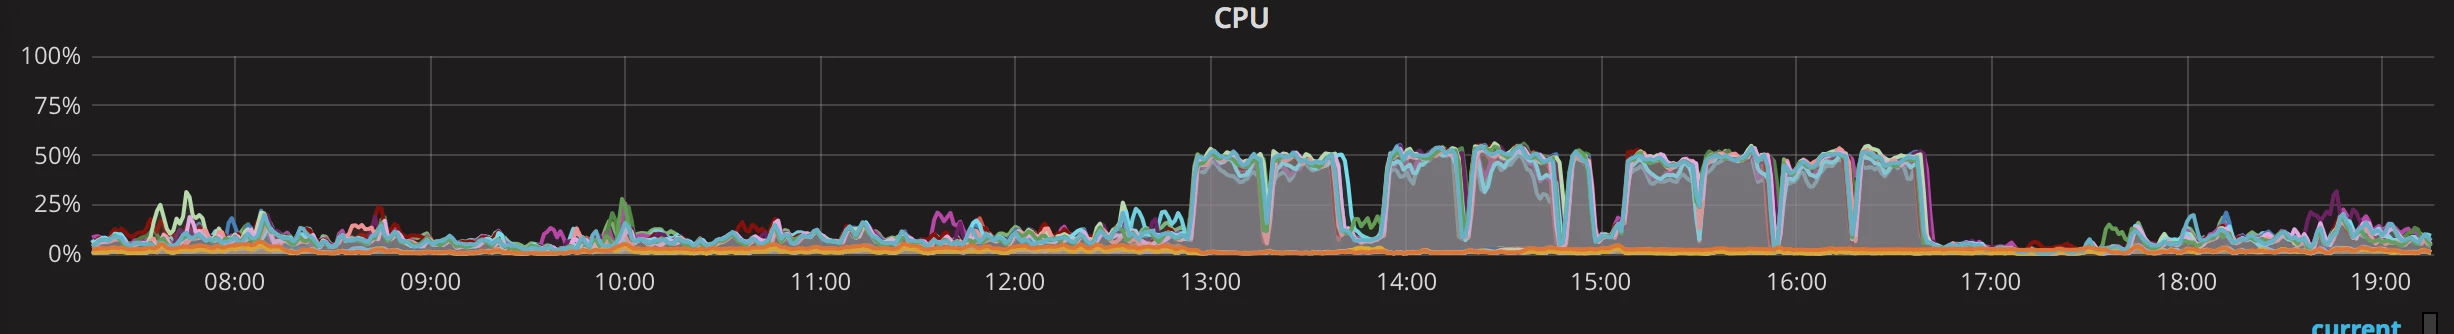
We are trying to find out reasons of that behavior.
Our observation and checks:
1. We observe great growth of waiting global catalog. Throughput of GCL significantly decrease.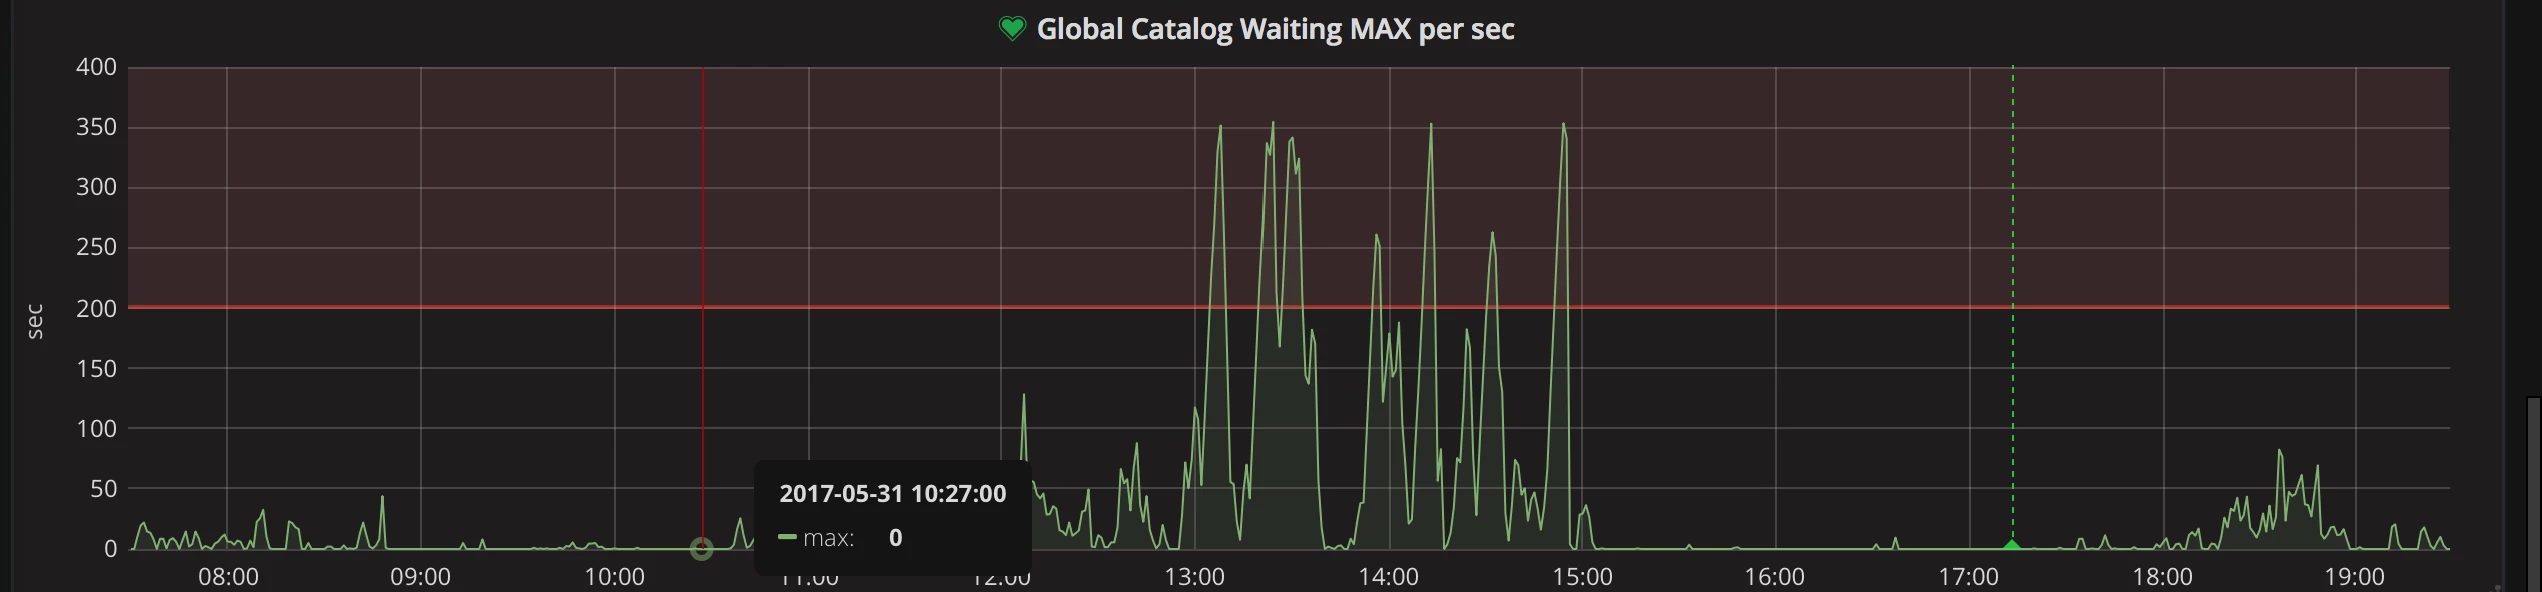
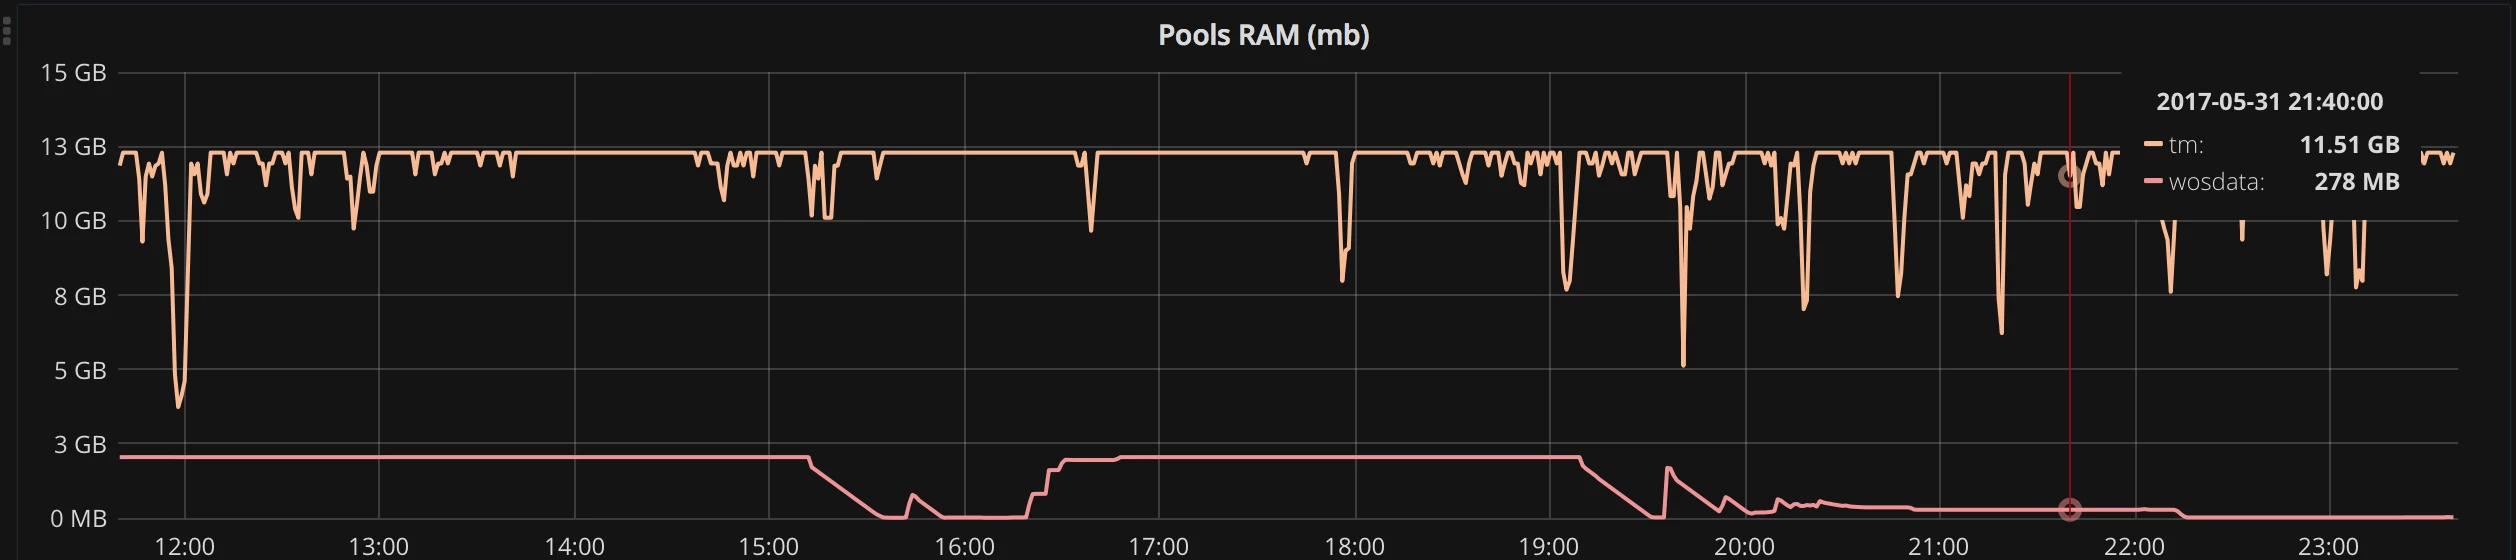
2. RAM, Threads, FileHandles, Network consumption does not differ from usual day.
3. TM does not have any queue. It operates as usual. We can't see any unusual TM operations. 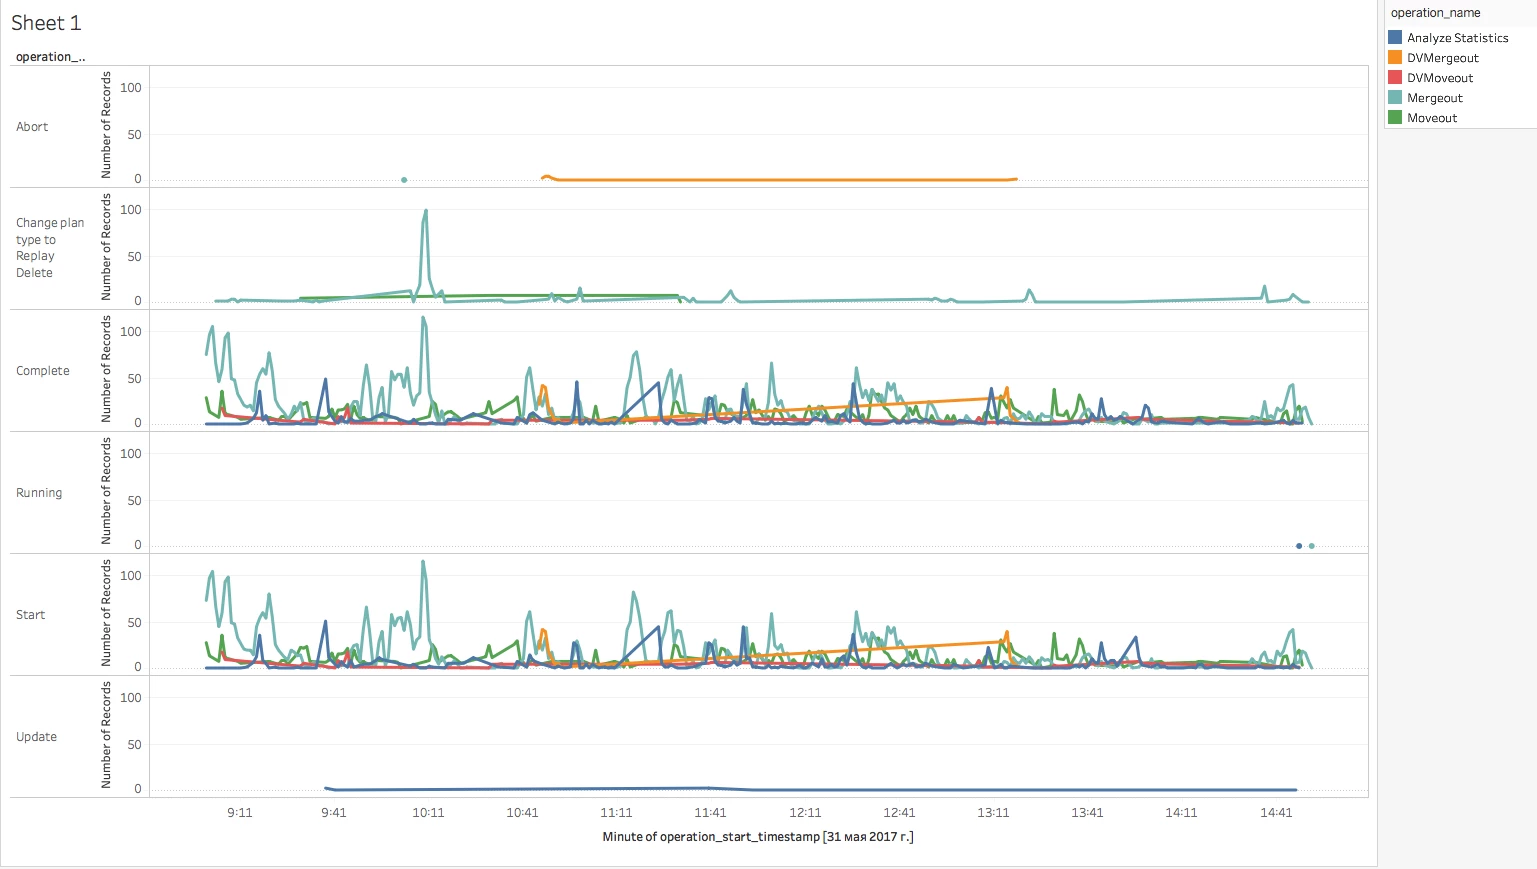
4. We checked all queries in sessions and system_sessions. All as usual, nothing suspicious. System services table shows us usual normal run rate.
5. We don't have any rebalance, partition reorganize operations while problem occurence.
6. We check all data_collector tables (about 200 tables). No success.
7. We can observe light correlation with disk latency. When cpu usage have short gap, disk latency significantly increase. 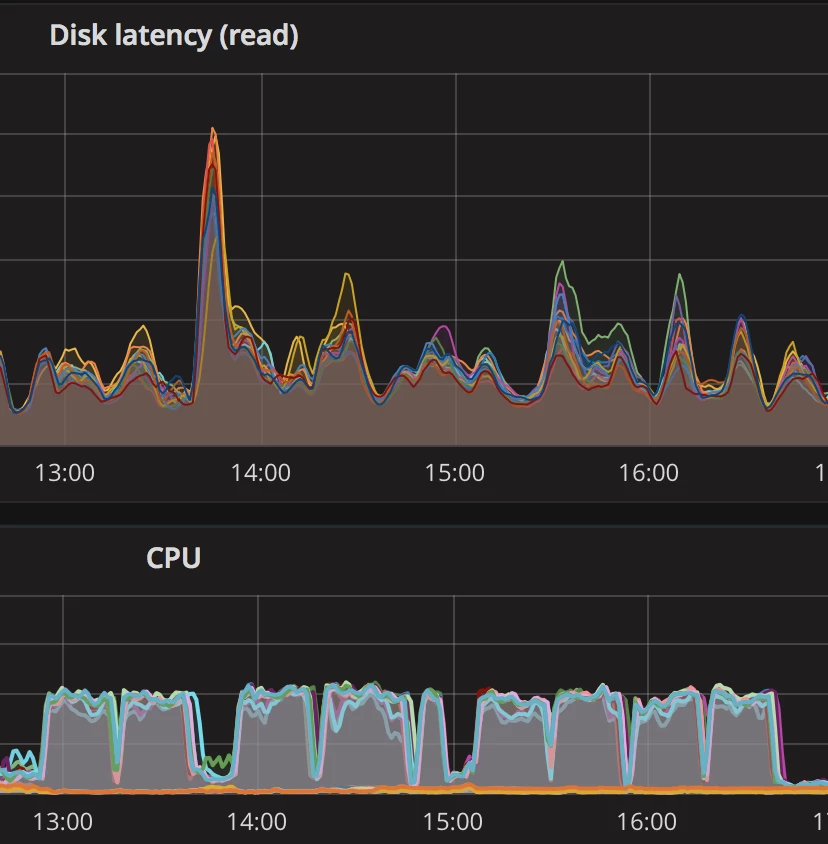
8. Used disk space slightly grow while high cpu usage.
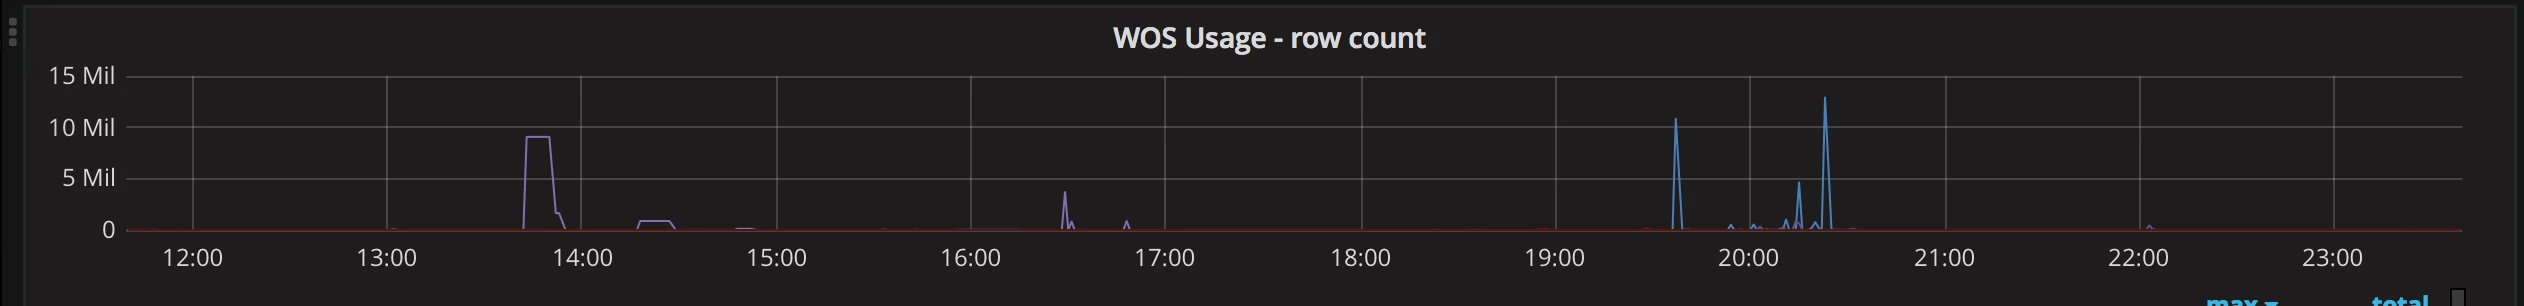
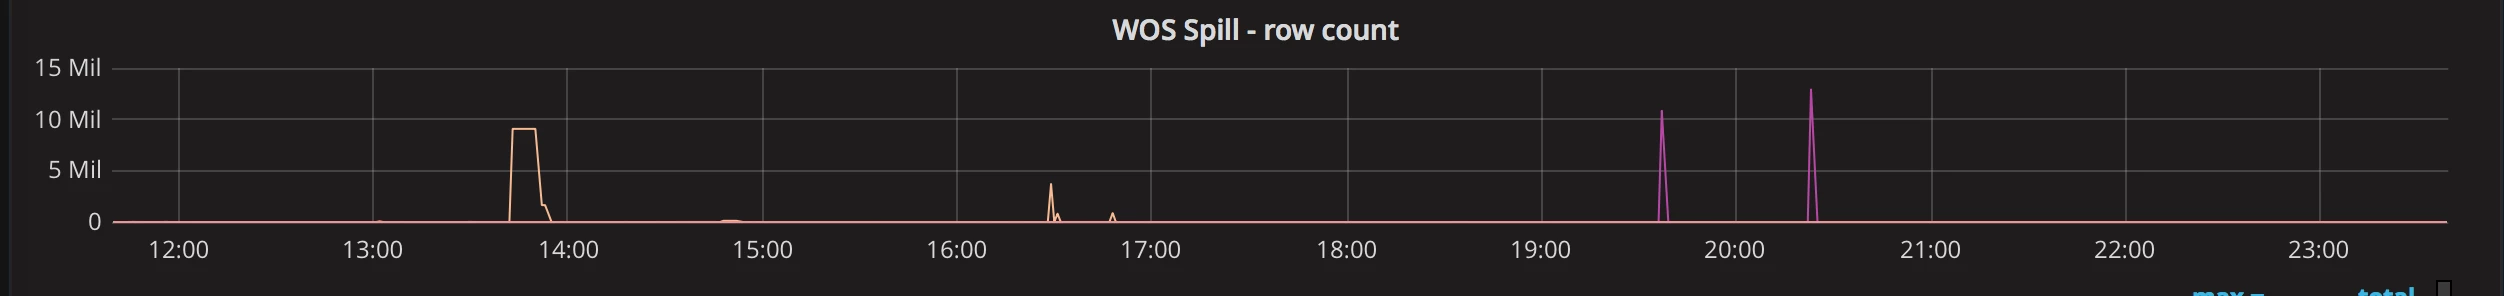
9. WOS usage as usual.
Can anybody suggest us some ways to determine the reason of problem?
Thank you.