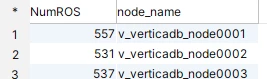
Hi I have a table which now contains > 1Billion records equallly distributed on a 3 node vertica cluster.
More details :-
1. Table holds data for 180 days and data is partitioned by a date only column
2. data for current day (about 15-20M records) is loaded into the table consistently in batches of 10k records at once using COPY statement
3. Zero deletes / update queries are run on the table
4. total table size is now about 2.5TB
5. all the queries on the tables is based on a column (which is the column in where clause of the query) which is part of the projections order by clause
when the table had about 250M records in total , queries ran under 200ms every single time , but now the same queries are going beyond 2-3secs (sometimes 9-10seconds!) most of the times
when I pick the slow running queries and run them with PROFILE keyword I dont see the slowness .
What could be the reason for such change in performance? Is it because of huge data volume ?